PYSPARK STARTER KIT
Build the pipeline instead of copying isolated snippets.
Run a small PySpark project that cleans sales data, joins customer details, calculates totals and writes Parquet. Then change it yourself using the supplied exercises.
Save 10%: use code PYSPARK10 at checkout and pay £17.10.
One payment through Payhip. Download the ZIP immediately after checkout.
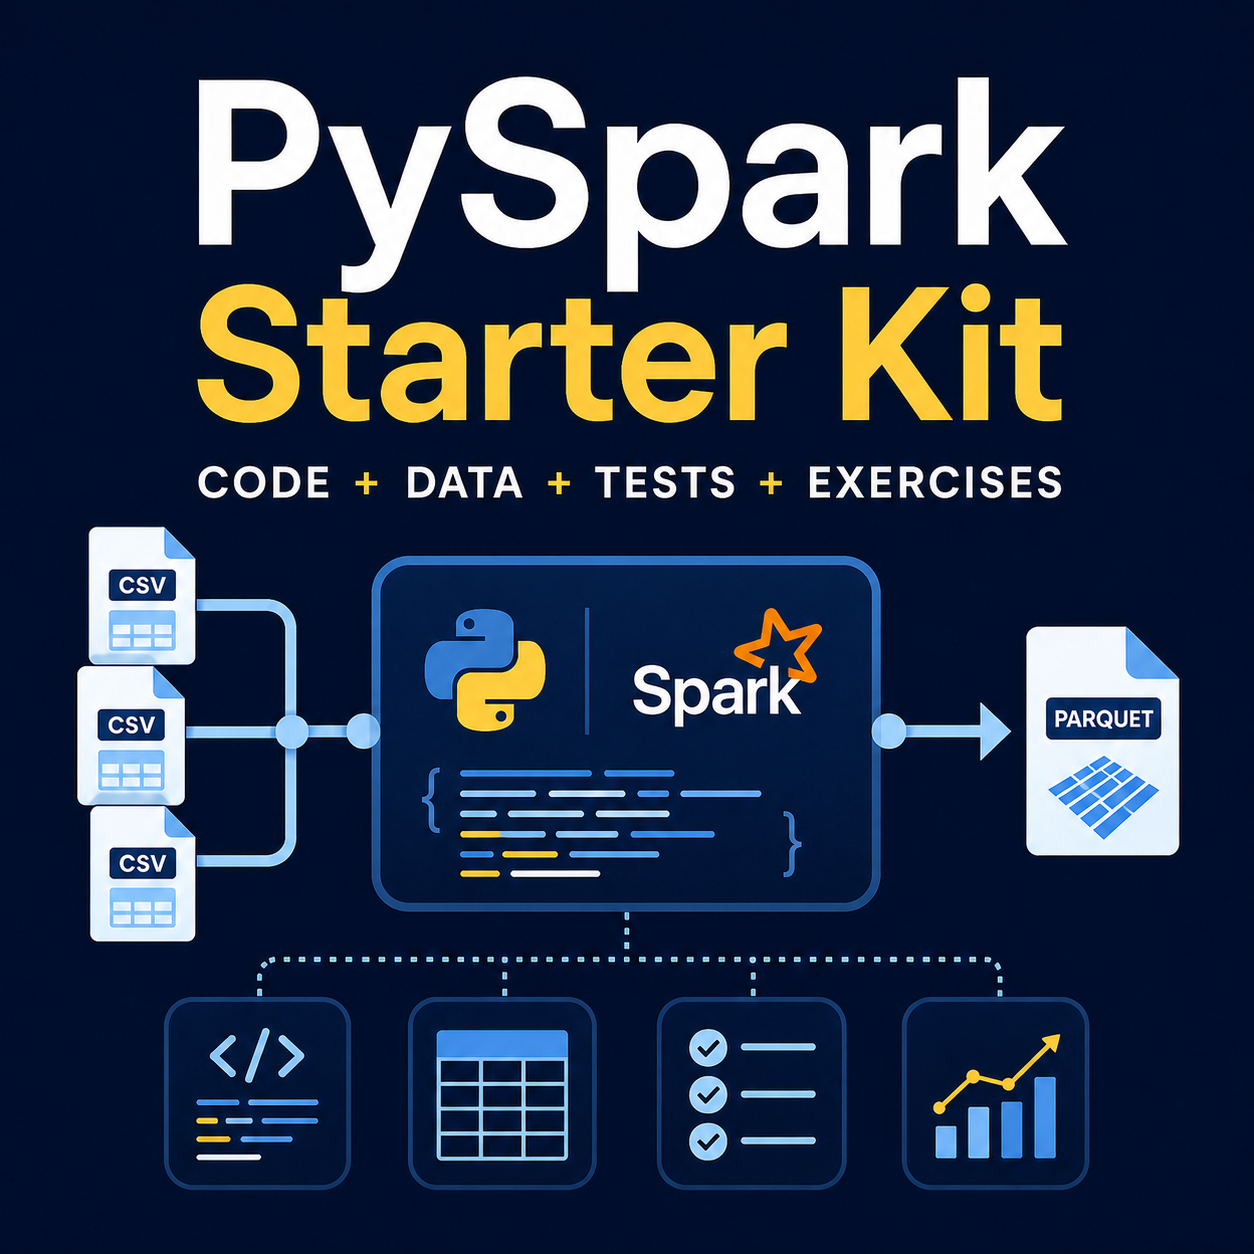
What you will have running
- Explicit schemas for two CSV inputs
- Missing-value and duplicate handling
- A left join that keeps unmatched sales
- Calculated gross and tax columns
- Parquet output and automated tests
TESTED, NOT THEORETICAL
The example contains problems on purpose
The input contains a missing tax amount, a duplicated transaction and a customer without a lookup match. The tests check that the pipeline deals with each case correctly.
2 tests passed

valid IDs: 101, 102, 103, 104
duplicate 104: removed
missing tax 105: removed
David lookup: NULL, sale retained
Parquet write: verified
INSIDE THE ZIP
Every file has a job
Guides and reference
- Mastering the Basics PDF
Clusters, DataFrames, lazy execution and first transformations. - Beyond the Basics PDF
Schemas, cleaning, joins, Parquet, workflows and the Spark UI. - Schema and joins cheat sheet
The syntax and checks you are likely to forget.
Working project
- Pipeline source
A complete CSV-to-Parquet command you can modify. - Notebook
The same workflow split into inspectable stages. - Sample datasets
Sales and customer CSV files with realistic data faults. - Tests, exercises and solutions
Check the behaviour, then make five changes yourself.
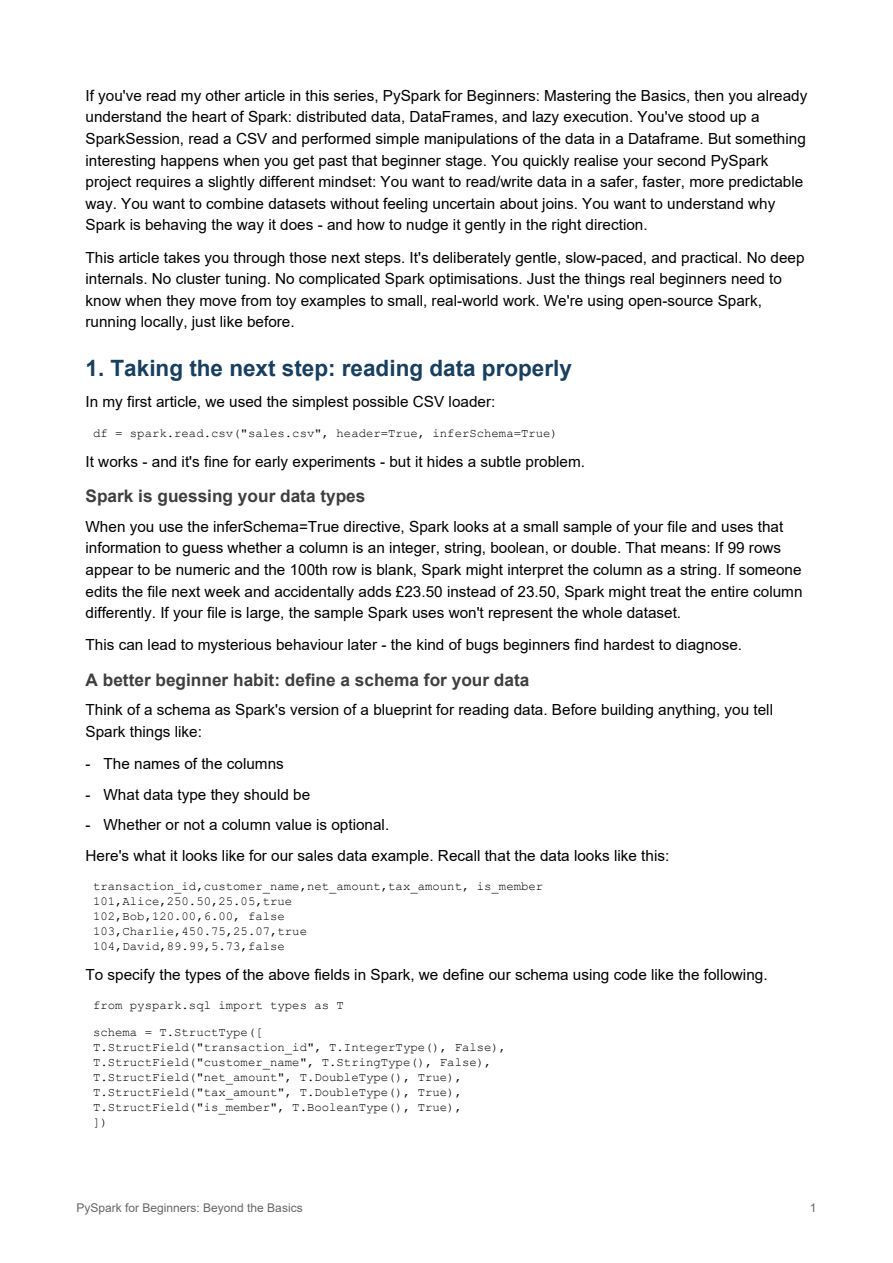
A REAL PAGE FROM THE PAID GUIDE
Define the schema before reading the file
The guide explains why `inferSchema=True` can produce different types when input changes. The project then gives you the exact schema and a failing-data mode you can run.
sales = (
    spark.read
    .option("header", True)
    .option("mode", "FAILFAST")
    .schema(SALES_SCHEMA)
    .csv("data/sales.csv")
)
Before you buy
You need basic Python, Python 3.10 or newer, and Java 17 or newer. The easiest tested Windows route uses Docker Desktop. macOS, Linux and WSL users can install PySpark into a virtual environment.
This kit teaches a local batch pipeline. It does not cover cloud cluster deployment, streaming, production tuning or Spark administration.
Save 10%: use code PYSPARK10 at checkout and pay £17.10.